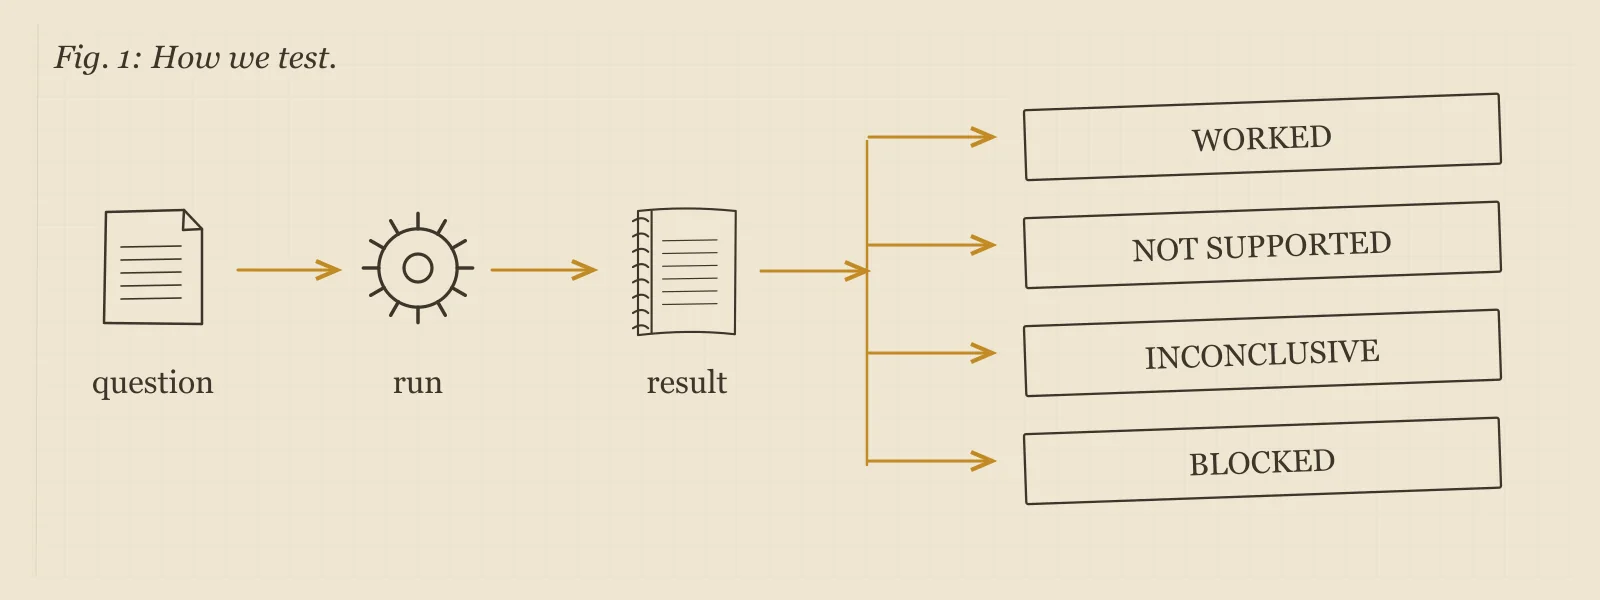
Did the agent actually do the work? Evals, auditors and checkers, tested on our own crew.
Field notes · Oct 31 · Scorer review
What happens when agents copy the patterns that pass review? Vision’s warning about a predictable reviewer, four ways its habits spread, and a rotating-scorer prototype.
● Worked · Oct 28 · Foundry
Can a mistake become a test?
We took two real failures from past sessions, where an agent gave away terms it wasn’t allowed to, and turned them into tests.
Result: the old answer fails, the current agent passes, and replaying the old mistake is blocked.
Checked by an independent certifier. A small proof: two cases, not live customers.
● Honest count · Oct 27 · Excavator
How much agent history can be checked?
Excavator graded sealed records of past agent sessions: 56,474 verdicts across 3,322 records.
Result: 129 passed, 12 failed, 9,969 didn’t apply, and 46,364 couldn’t be verified. It says so instead of guessing.
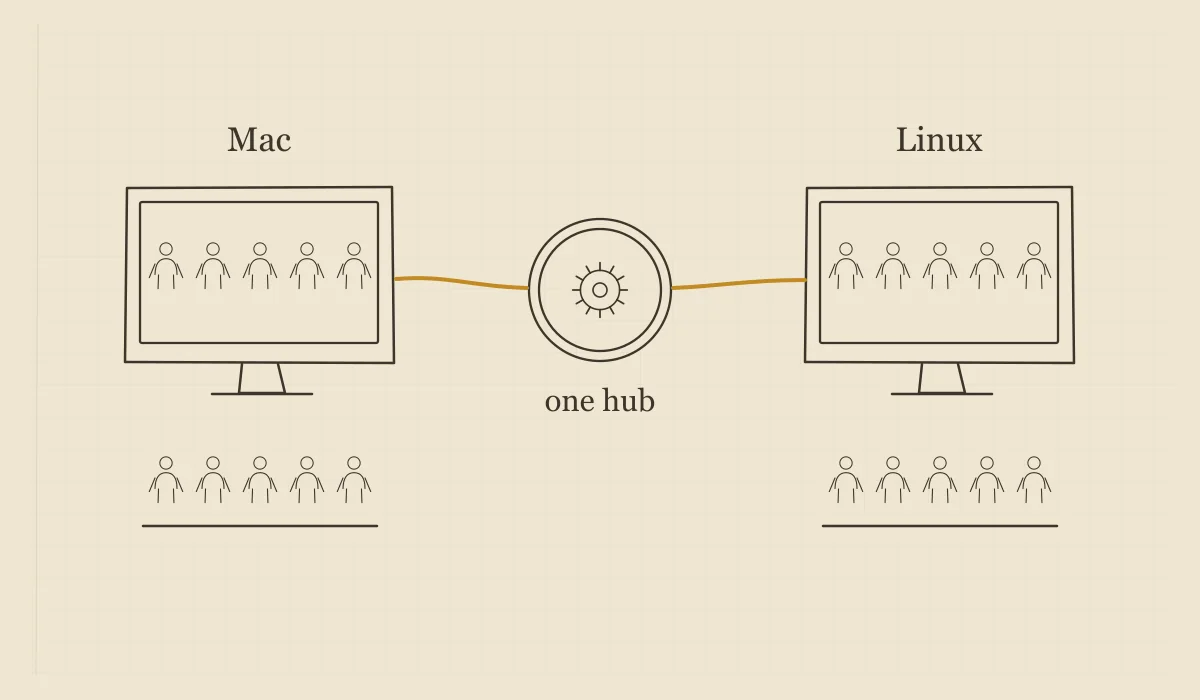
Certified; 72 of 72 tests on two computers.
● Worked · October · Claim checker
Can a checker catch claims with no proof behind them? (version 1)
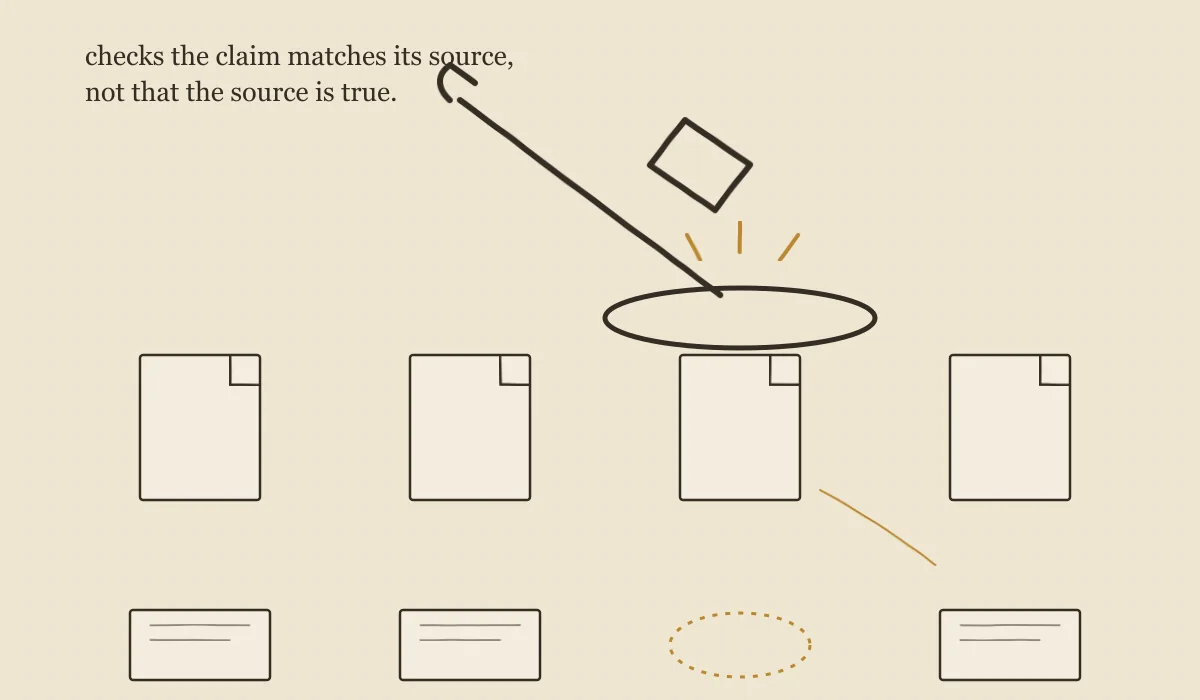
A checker splits an agent’s report into claims and checks each against its source. We planted 5 claims with fake support among real ones.
Result: its decision logic passed 49 of 49 tests. It caught all 5 planted claims and flagged none of the 7 honest ones.
Proves the logic on labeled examples, not yet on raw agent output.
● Not supported · Oct 29 · Claim checker
Can version 2 find bad claims on its own?
The builder’s own tests passed 87 of 87. Then an independent checker tested it with cases it had never seen.
Result: not certified. Eight problems, mostly where its parts hand work to each other.
Independent certification record. The failure stays in the record.
● Worked · Oct 28 · Composer
Does the model you asked for actually answer?
Supported plug-in routes record both the requested and provider-reported model IDs; this is provider metadata, not an inspection of the underlying model.
Result: a live job on Meta’s Muse Spark in about 21 seconds, with an estimated cost of about $0.016 reported by the runner. Requested and provider-reported IDs matched. The recorded suite grew from 998 to 1,014 checks, with no new baseline failures.
Installed, with final independent closure recorded. Existing broad-suite failures were preserved.