● Sept 26
One review, start to finish
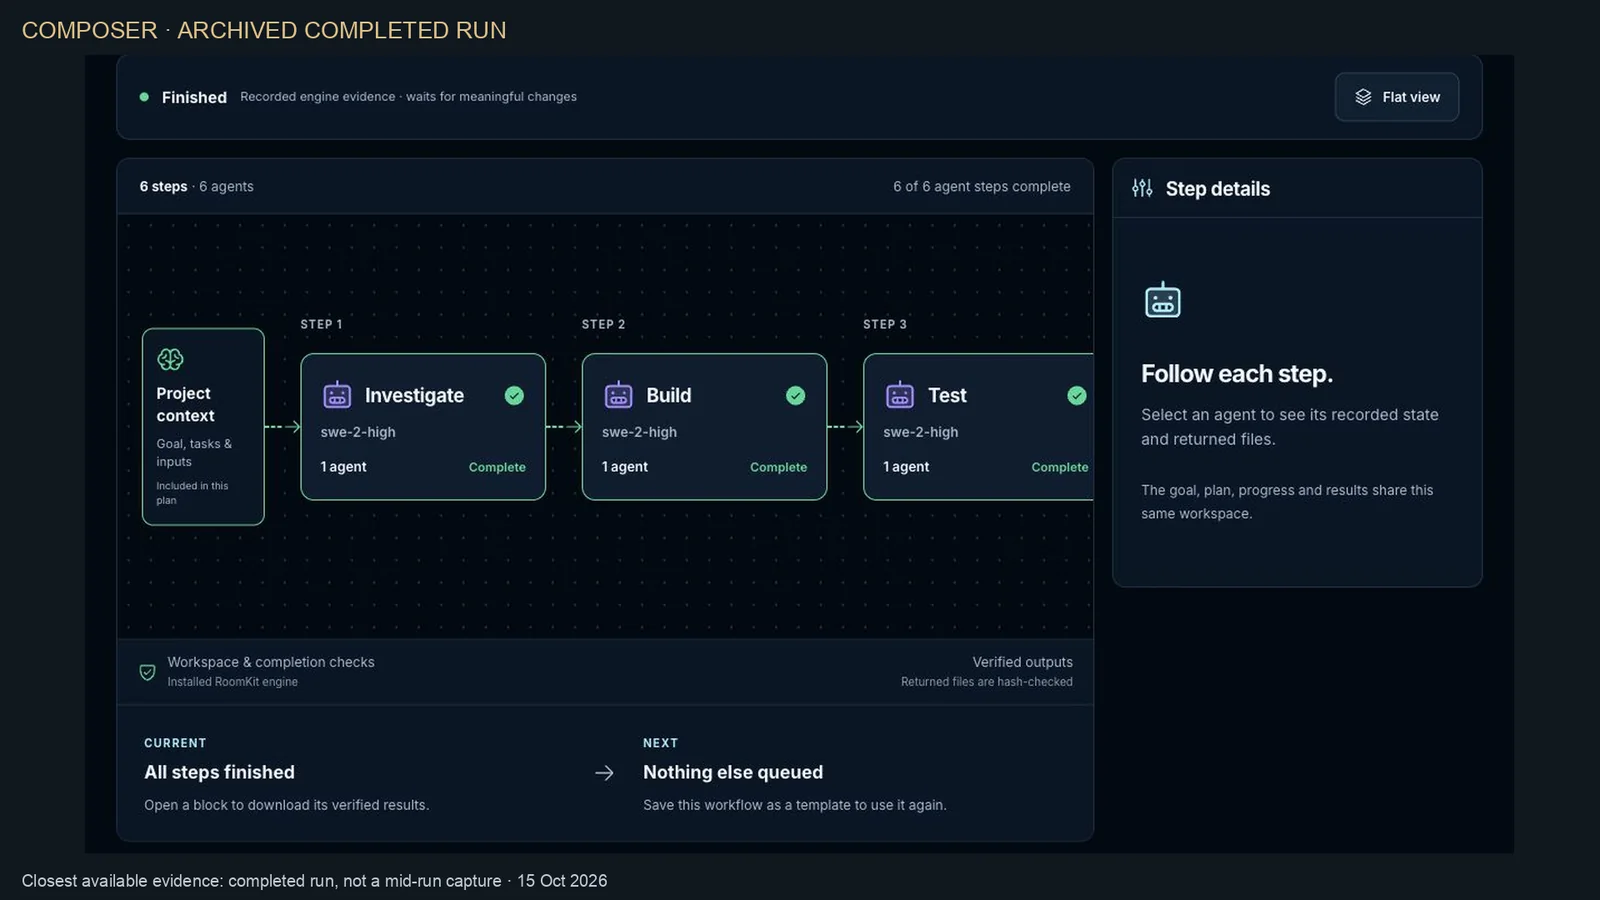
Seven blind reviewers from two AI model families found 18 problems. Sixteen were fixed; two were put off on purpose, with reasons.
Follow the recorded run →Tools · Our own agent factory, in daily use
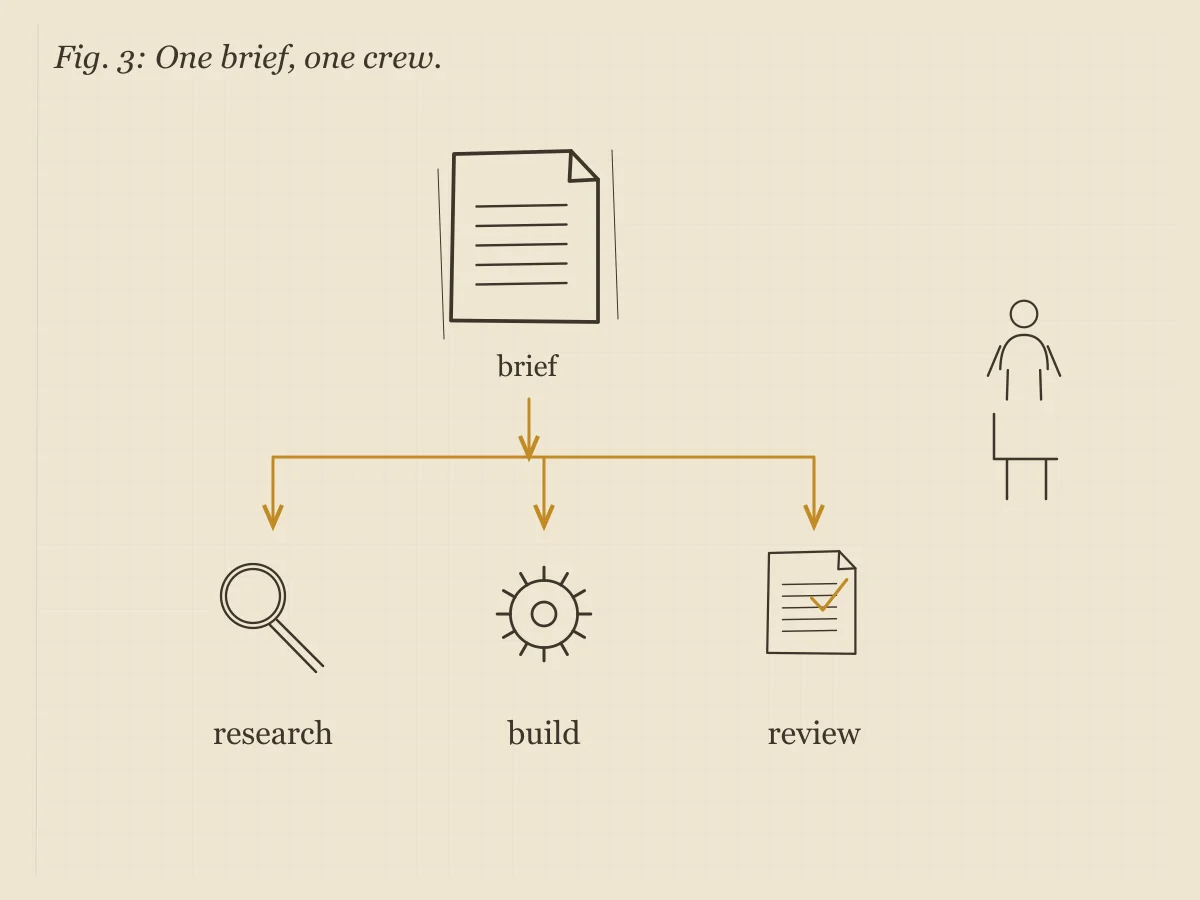
Composer turns one job into a plan a crew of agents can carry out: research it, build it, then try to break it. The agent that built it never grades it.
Installed privatelyMac and Linux workers, one coordinating hub. Updated October 30, 2026.
01 · Plan the crew
I watched one of my agents coordinate a job by hand: picking workers, briefing them, checking on them and gathering their results. Composer does that part. Lay out who researches, who builds and who reviews, in order; Composer launches them, tracks them and collects what comes back. My agents were its first users.
02 · Models and provider routes
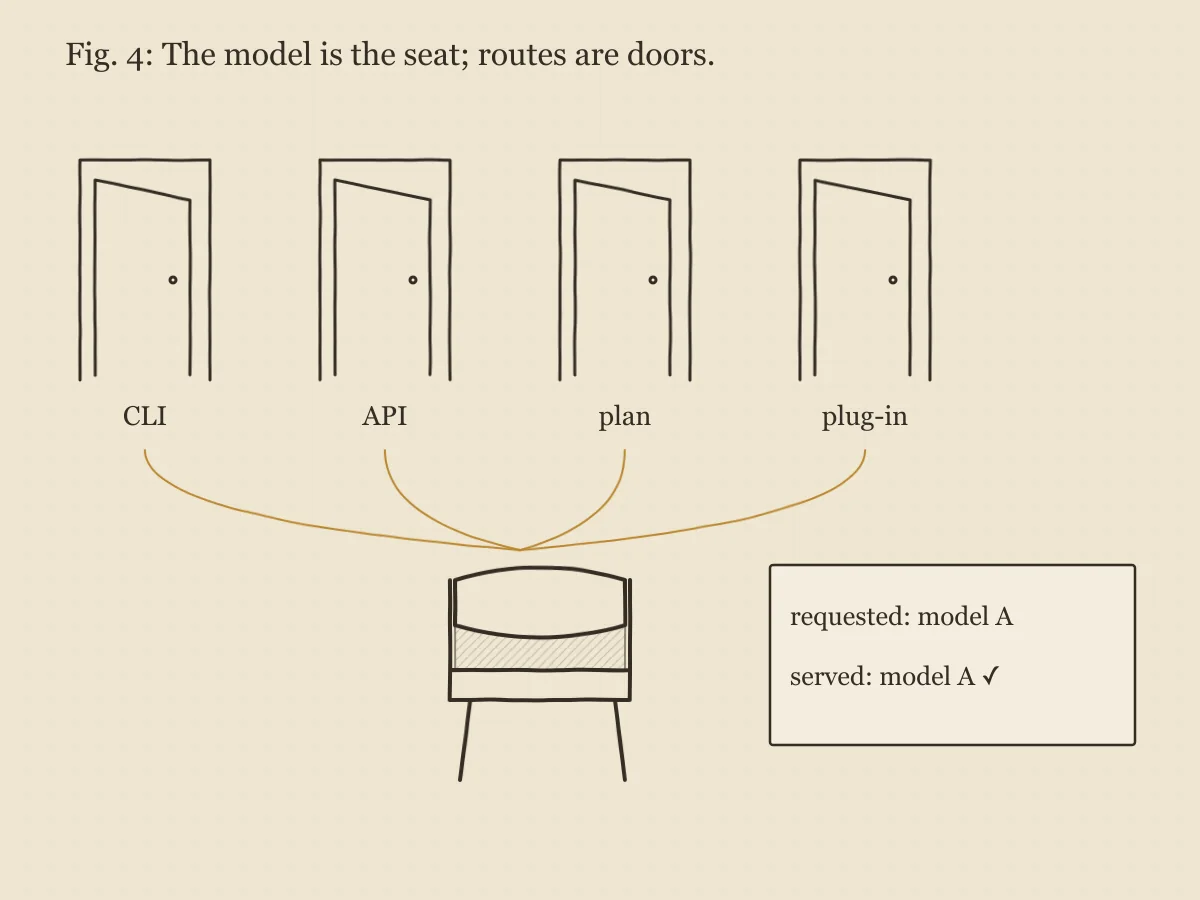
Models from several AI companies work side by side. Compatible OpenAI-style chat APIs can be added by configuration; other protocols need adapters. Supported plug-in routes record the requested and provider-reported model IDs and flag a mismatch. That records what the provider reports, not an independent inspection of its model.
03 · Checked by the other side
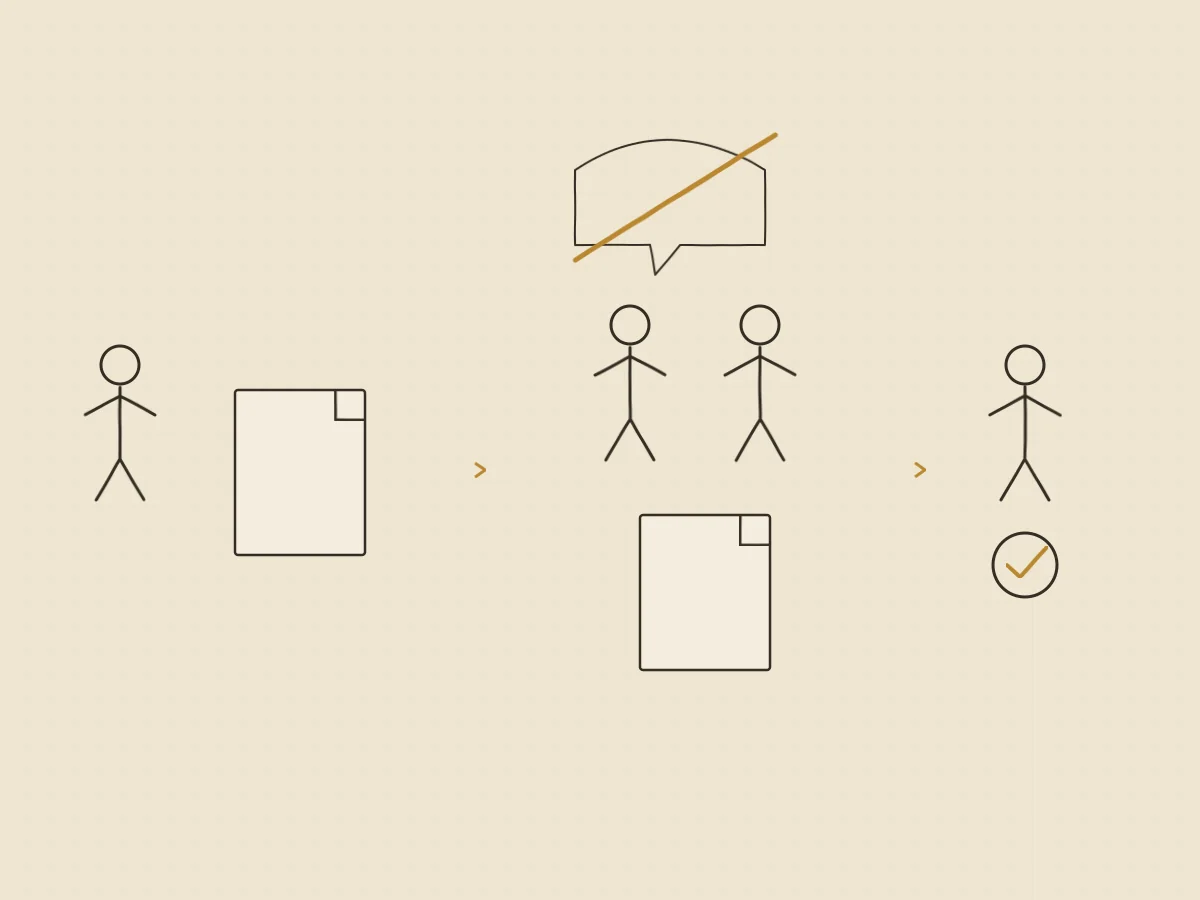
The builder tests and reviews its own work; then a reviewer from a different AI company checks it, often blind: it sees the work, not the builder’s explanation. We use a fresh reviewer from another model family to bring a separate perspective.
04 · Nothing runs by surprise
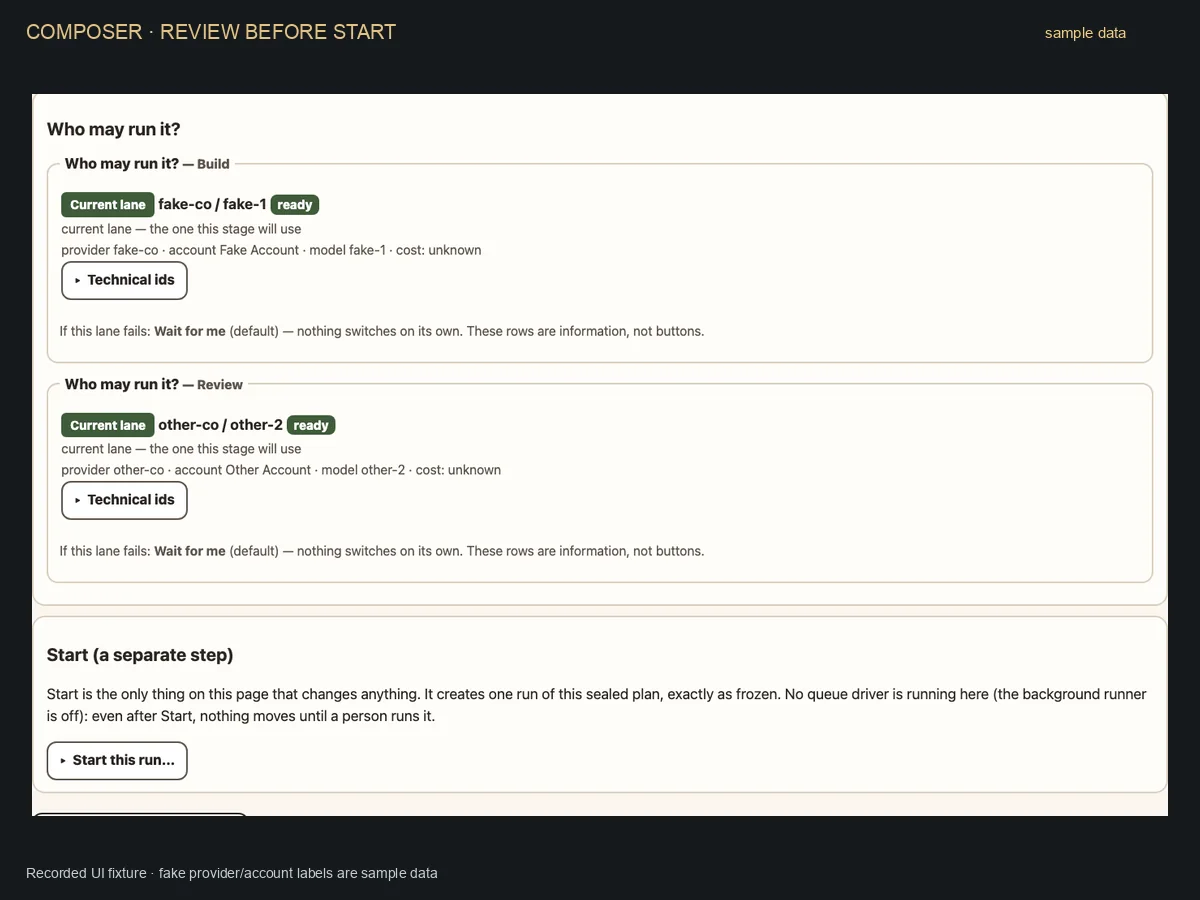
A person or an approved agent can set up a run. Reading a project doesn’t grant permission to launch it. Nothing starts until someone reviews it and presses Start, and the run that starts is the one that was reviewed.
05 · A record of every run
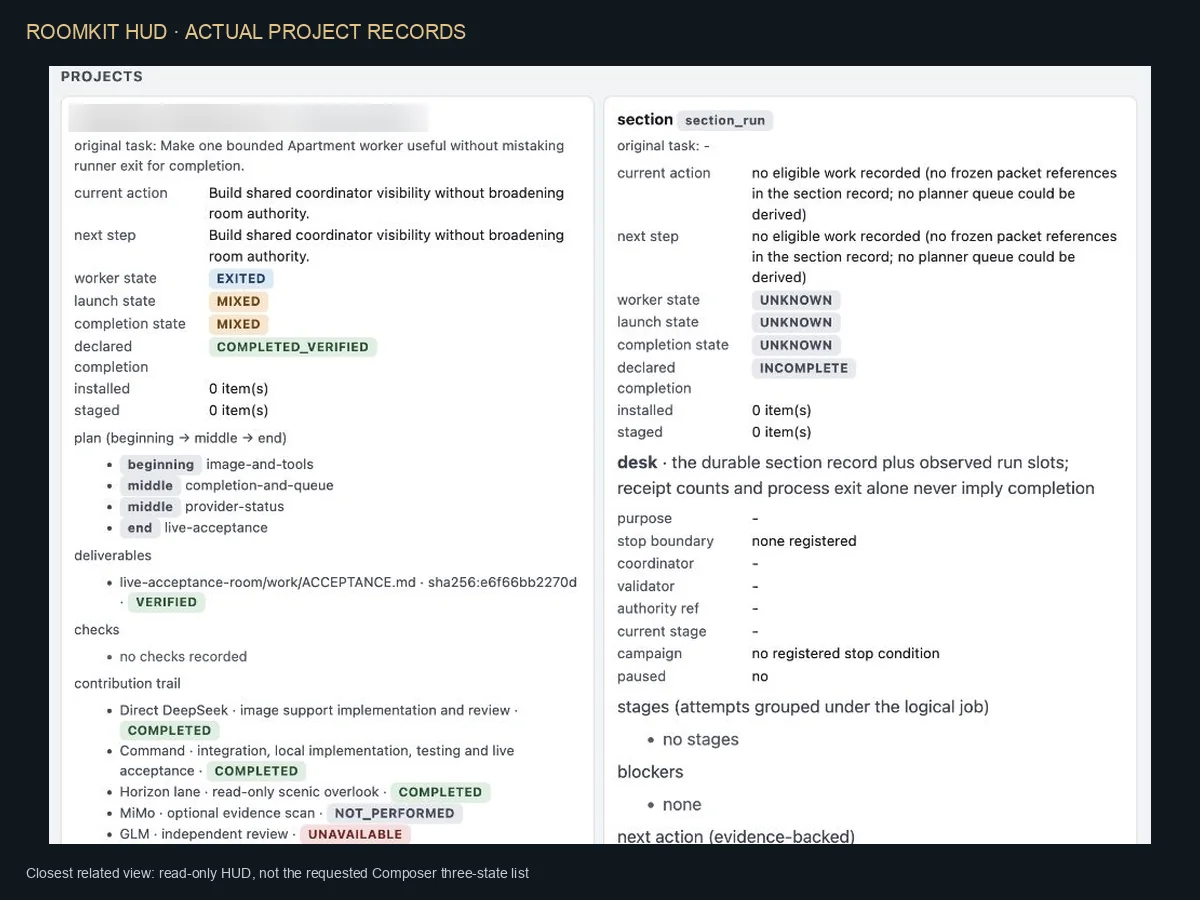
Every run keeps its record: what was asked, who did it, what came back and what was checked. Failures stay in, so the next project starts from what actually happened.
Results, failures included
● Sept 26
Seven blind reviewers from two AI model families found 18 problems. Sixteen were fixed; two were put off on purpose, with reasons.
Follow the recorded run →● Partial
A recorded Video Evidence Engine job returned useful research, but its repair stage errored and produced no verified patch. A useful partial result is still partial.
● Blocked
An October comparison stopped after two Start timeouts, with zero workers dispatched. Its cause is unknown, so it stays blocked rather than becoming a duplicate.
Design choices
Separate the review from the build, and keep a record of the provider route.
Independent review
Builders test and review their own work first.
Then a fresh review
A separate agent checks the work; the September 26 run used two model families.
Model receipts
A request alone does not establish which model answered.
Supported plug-in routes
Receipts retain requested and provider-reported model IDs, with a mismatch flagged.
Where it stands
Composer is our private workflow tool; it isn’t available to install. Installed jobs have used native workers and provider plug-ins. The text plug-ins return text; they don’t give a model a filesystem, browser or executed tool loop. We haven’t measured a general speed-up or how much operator intervention each finished job saves.
Composer is our own tool. The thinking behind it, crews from rival AI companies, checks they can’t skip and a record of every run, is what I bring to a team.
A dated working report, not peer-reviewed research. Read it as Markdown · Meet Foundry →