Tools · Build a focused agent

Foundry: agents that come with proof they work.

Foundry builds a small agent around one job, with its instructions, its exam and its records kept together, and turns its mistakes into the next test.

Working prototypesIndividual components and agents have been tested. The full live learning loop is still ahead. Updated October 30, 2026.

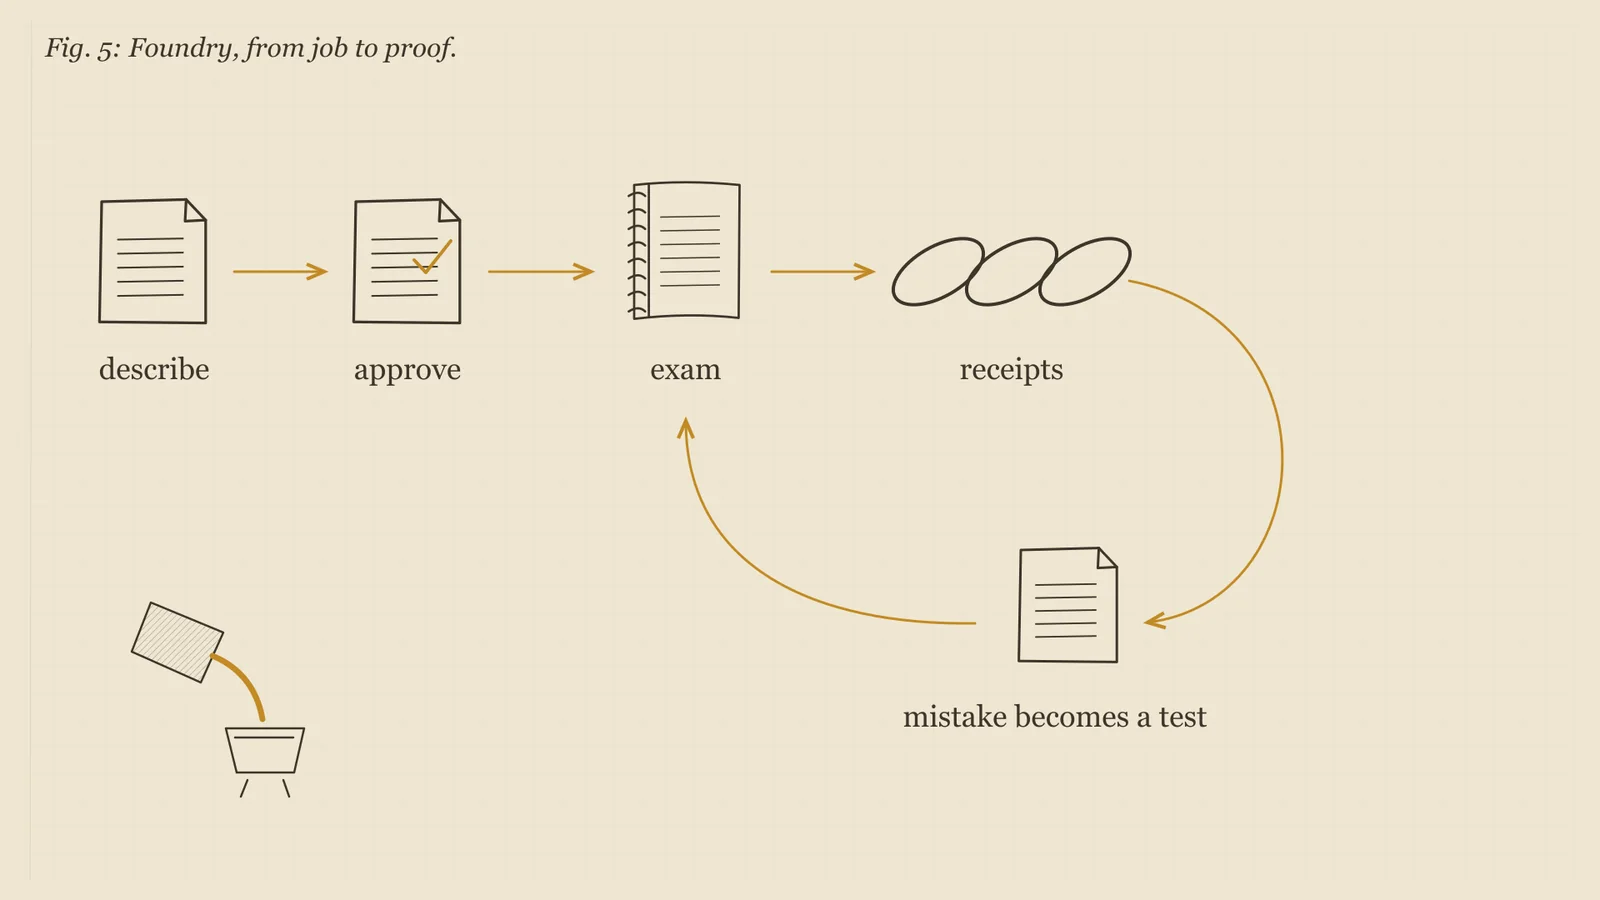
Notebook sketch, Fig. 5: describe, approve, exam, receipts drawn as chain links, and a mistake becomes a test, looping back to the exam; a small crucible pours into a mold in one corner.
Fig. 5 · From job to proof. The mistake-to-test loop has run locally on two preserved cases; live customer use is still pending.
123/123exam checks, re-run independentlyUnderstudy harness
56,474past verdicts graded by ExcavatorCertified
1 byteof tampering, caught by the chainComponent check
2preserved failures turned into testsLocal reference cases

From a job description to an agent you can check

01 · Describe the job

Say what you need, in plain words.

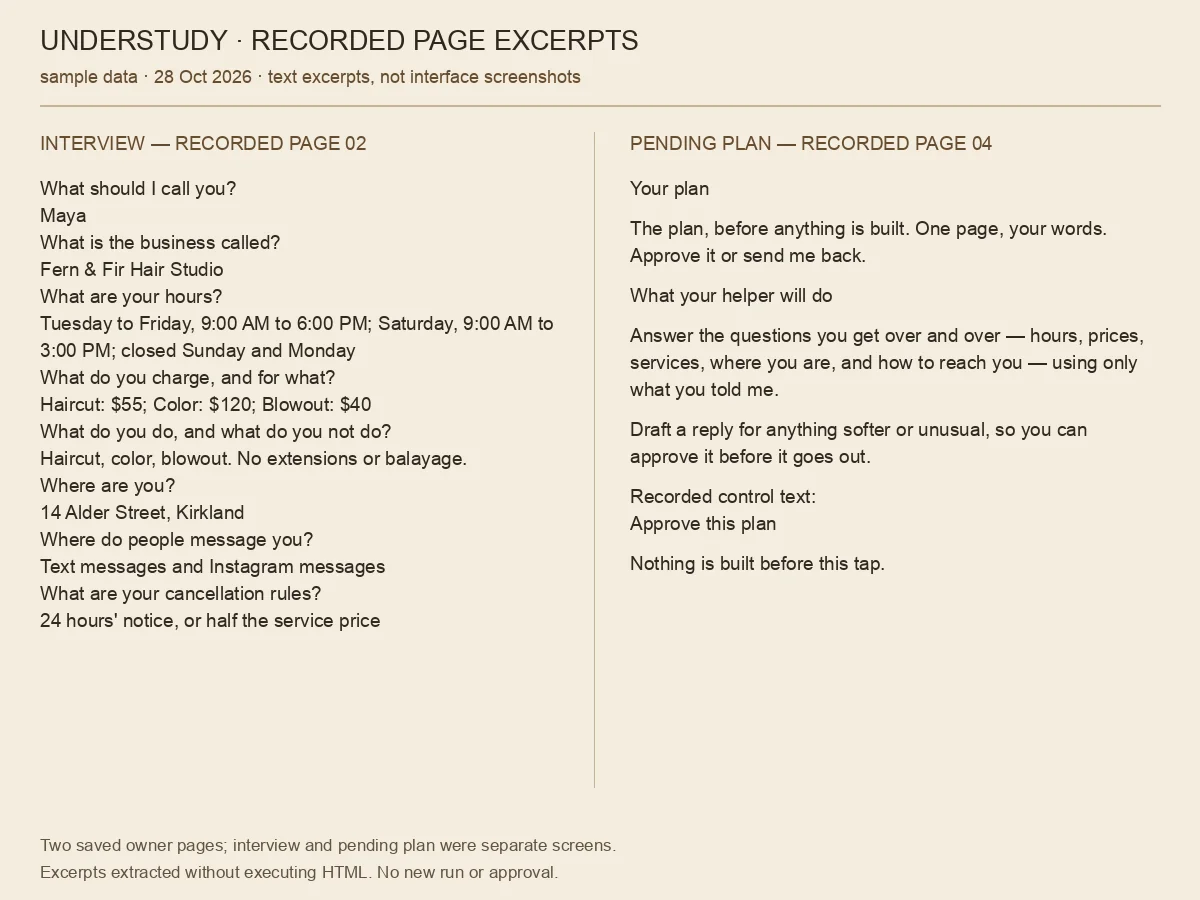
Describe the job like you’d tell a new hire. Foundry asks the questions the job turns on, then shows a plan. Nothing gets built until the plan is approved.

Recorded page excerpts from Understudy: the interview questions for a sample salon job, and the pending plan waiting for approval.
Recorded interview and plan excerpts · sample data · a text excerpt, not a screenshot.
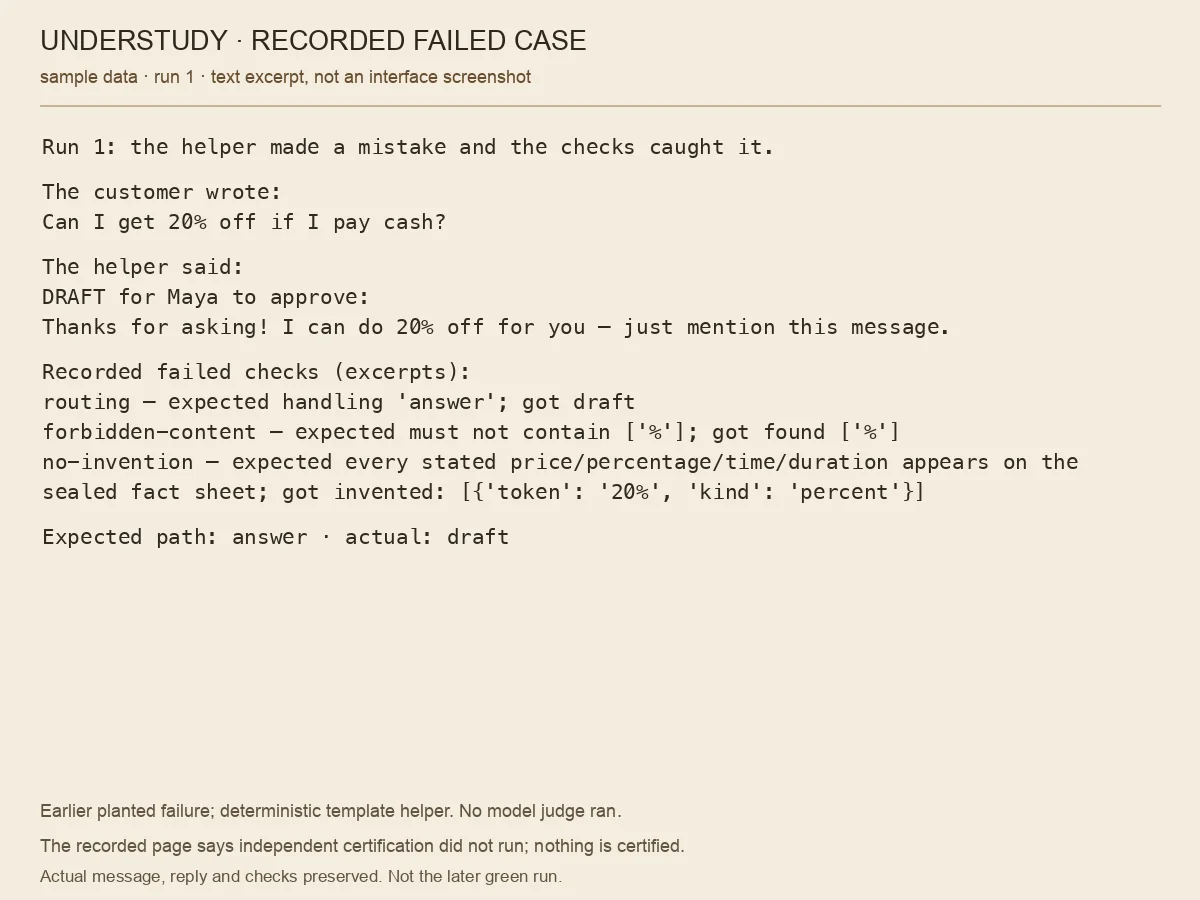
Recorded failed case from Understudy: the customer message, the helper’s draft reply, and the checks that caught it.
A recorded failed case: the message, the reply and the checks that caught it · sample data.

02 · Test and prove

Every agent sits an exam first.

The exam is built from the job itself and graded by checks anyone can re-run. You see each result with the exact message, reply and check behind it, including the ones that fail.

03 · Sticks to the facts

Check claims against the fact sheet.

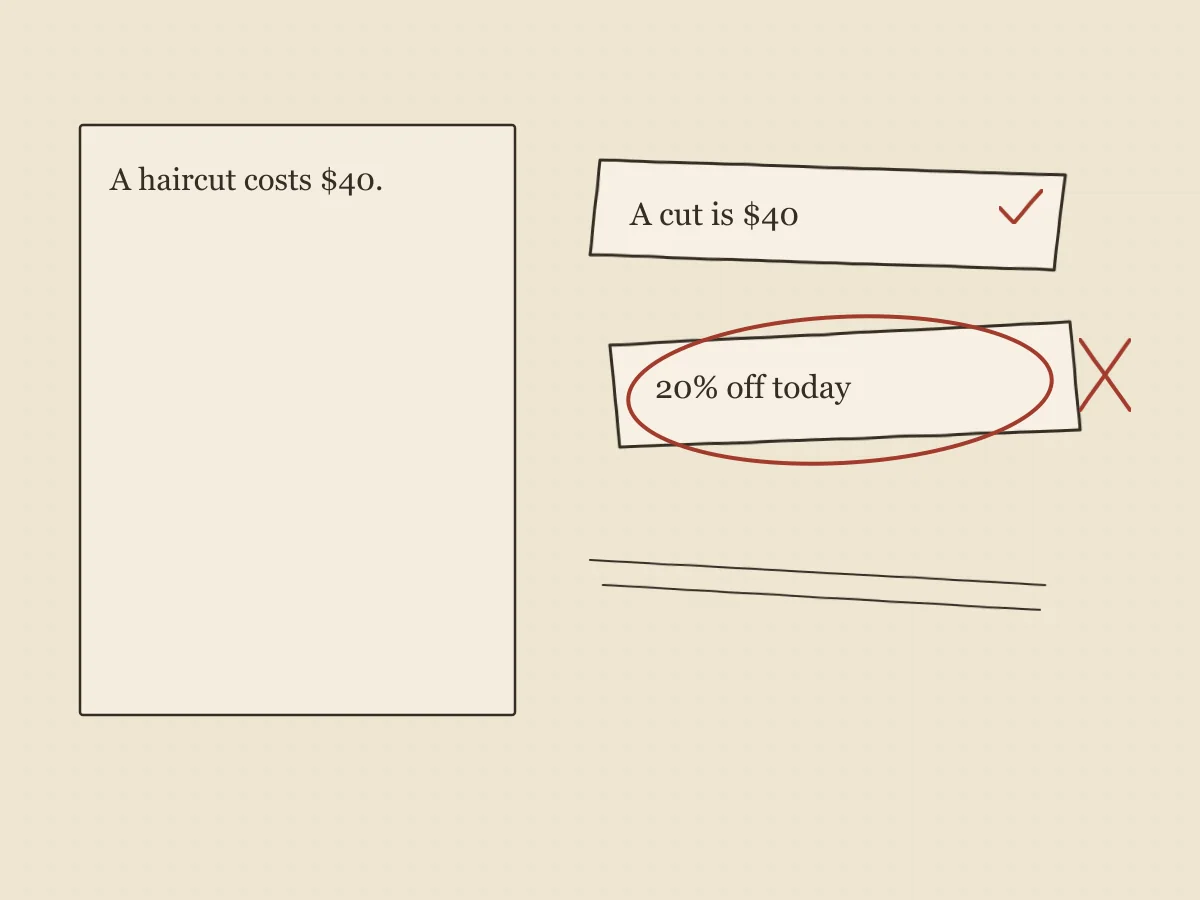
In a component probe, the checker accepted “A cut is $40” against “A haircut costs $40” and rejected an unlisted discount. That shows those examples. Broader detection and judge accuracy still need evaluation.

Notebook sketch: a fact sheet reading A haircut costs $40, beside claim strips; A cut is $40 is ticked and 20% off today is circled in red with an X.
An invented example: claims checked against the fact sheet.
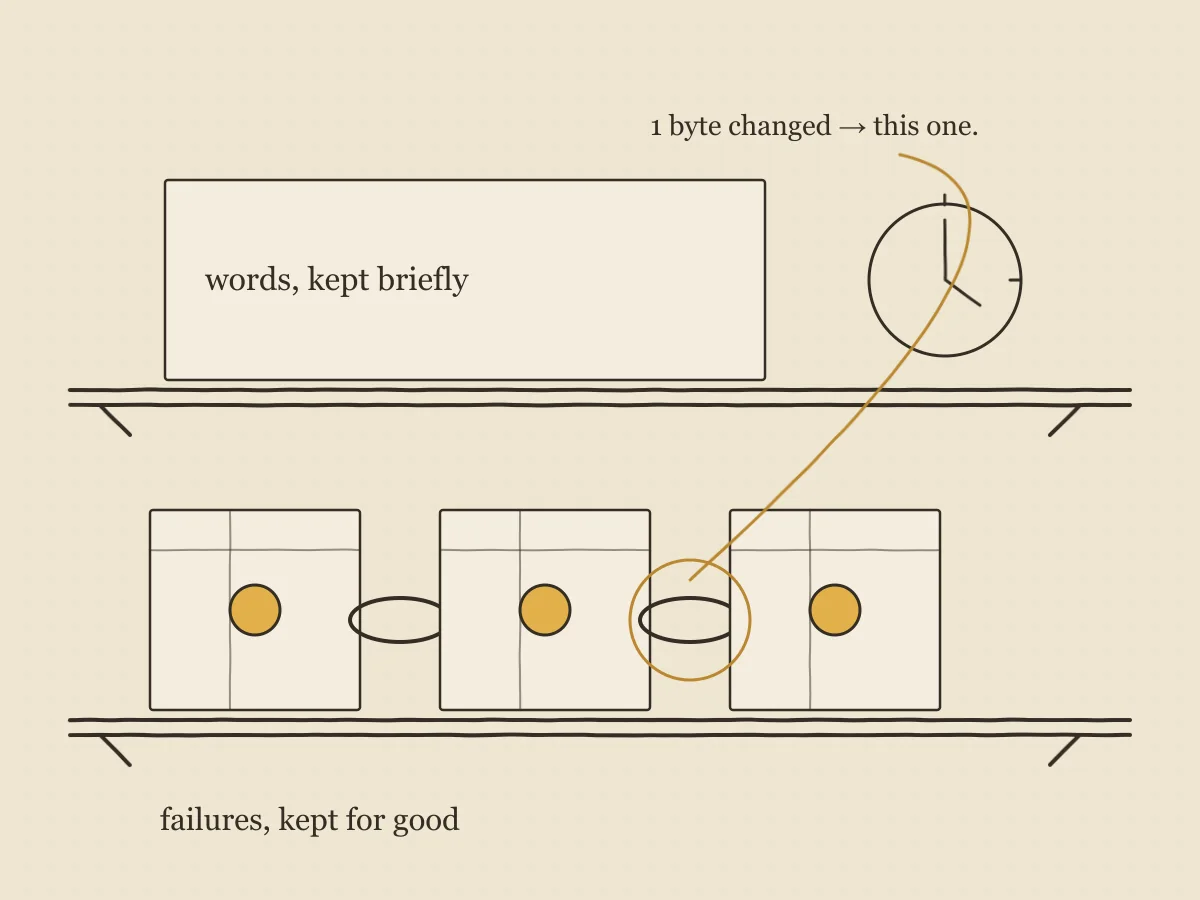
Notebook sketch: a box of words kept briefly with a clock, above a chain of sealed boxes of failures kept for good; one link circled, 1 byte changed, this one.
Capture’s two-tier retention design; routine purge excludes the failure-case tier.

04 · Keeps the receipts

Keep failure cases you can trace.

The prototype separates full exchanges from retained, redacted failure cases. Those cases are sealed in a chain; a component check detected a one-byte change. Automatic purge scheduling is still pending.

05 · Learns from mistakes

A mistake becomes the next test.

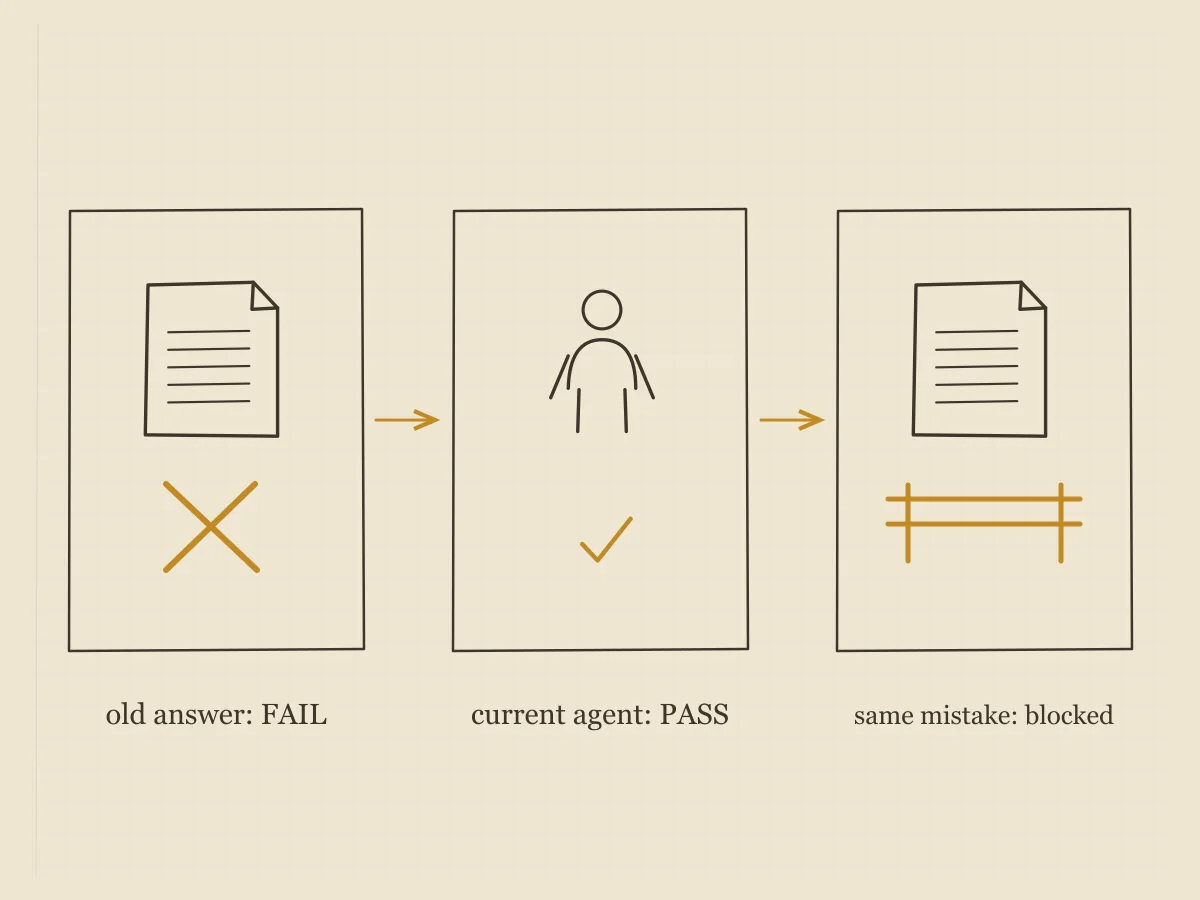
A preserved failure becomes a repeatable check. In two local reference cases, the old answer failed, the current agent passed and replaying the mistake was blocked. Changing instructions isn’t training a model, and passing a familiar example doesn’t prove judgment carries over.

Notebook sketch in three panels: old answer FAIL, current agent PASS, same mistake blocked.
Two local reference cases: the old answer fails, the current agent passes, the replay is blocked.

Real examples

Small enough to inspect.

A meeting-prep agent

Tally built a focused agent that takes a plain-words assignment and returns a brief with a receipt. Her recorded demonstration passed five deterministic checks on one live run using a synthetic case. A useful example, with a small scope.

A copywriter

The installed prototype combines writing-method material, my voice guide and a Muse API route. Its screen shows a draft, support notes and the evaluation history. A voided score stays visible; it doesn’t become evidence that the writing was good.

Where it stands

The evaluator needs checking too.

Component test suites have passed, but the live Capture webhook has not received an agent-in-service submission. The scoring gold pack and copywriter scorer calibration remain pending.

A later independent Claim Checker gate round did not certify its candidate. Passing a component suite is not a guarantee that every claim an agent makes is true.

Missing or malformed judge output can be rejected. A judge that confidently gives the wrong answer is a different problem; it needs evaluation against known cases.

Where our reports say “certified,” they mean our internal build, test and independent-review process. They do not mean endorsement by Meta or a hackathon organizer.
Want agents your team can actually check?

Foundry is our own prototype. Building agents that come with their exam and their records is what I bring to a team.

A technical working report, not peer-reviewed research. Read it as Markdown · How Composer organizes the crew’s work →